AI Doesn't Need Autonomy—It Needs Discipline
Applying SRE principles to AI agents through a controlled audit-plan-apply workflow with policy and human permission.
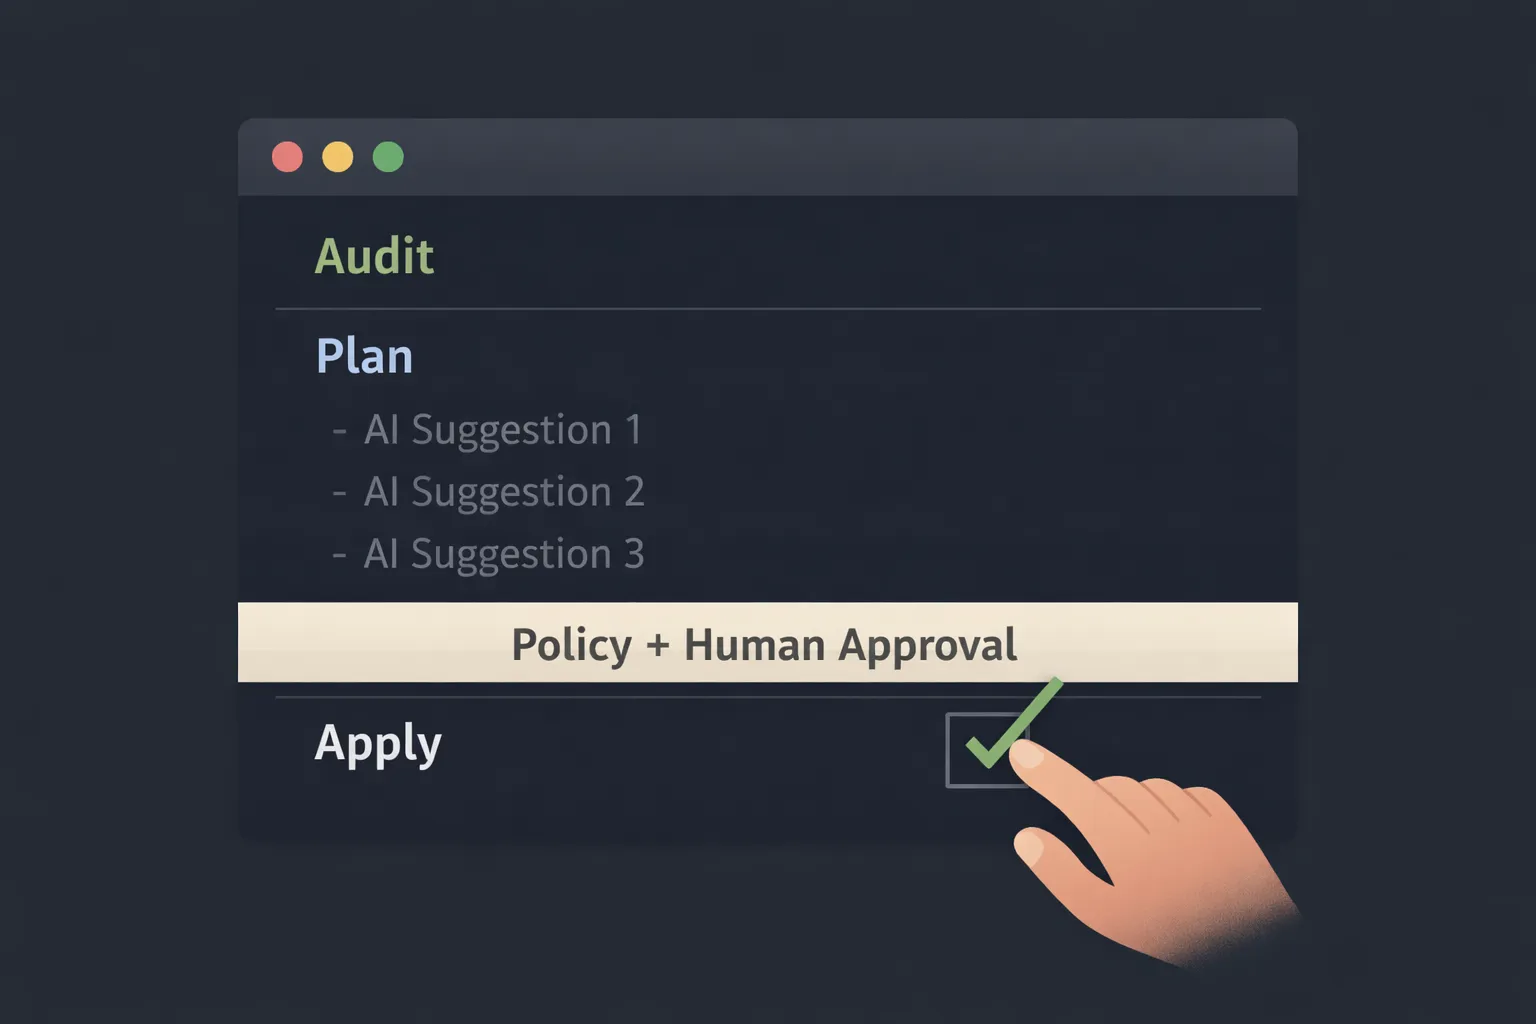
Technical illustration
Every AI agent demo looks impressive.
The assistant installs packages, fixes issues, restarts services, cleans disks—all without asking. It feels powerful. Magical, even.
And then you imagine it running sudo on your own machine. That’s where the excitement quietly turns into discomfort.
I like AI. I use it daily. I build with it. But when I tried applying autonomous AI agents to something very real—system maintenance on my Linux machine—I ran into a hard truth:
AI doesn’t need more autonomy. It needs discipline.
This article is about why I built a terminal-based assistant called Housekeeper, and what it taught me about designing AI that people can actually trust.
Code and details at https://github.com/pain459/housekeeper. Feel free to contribute ❤️
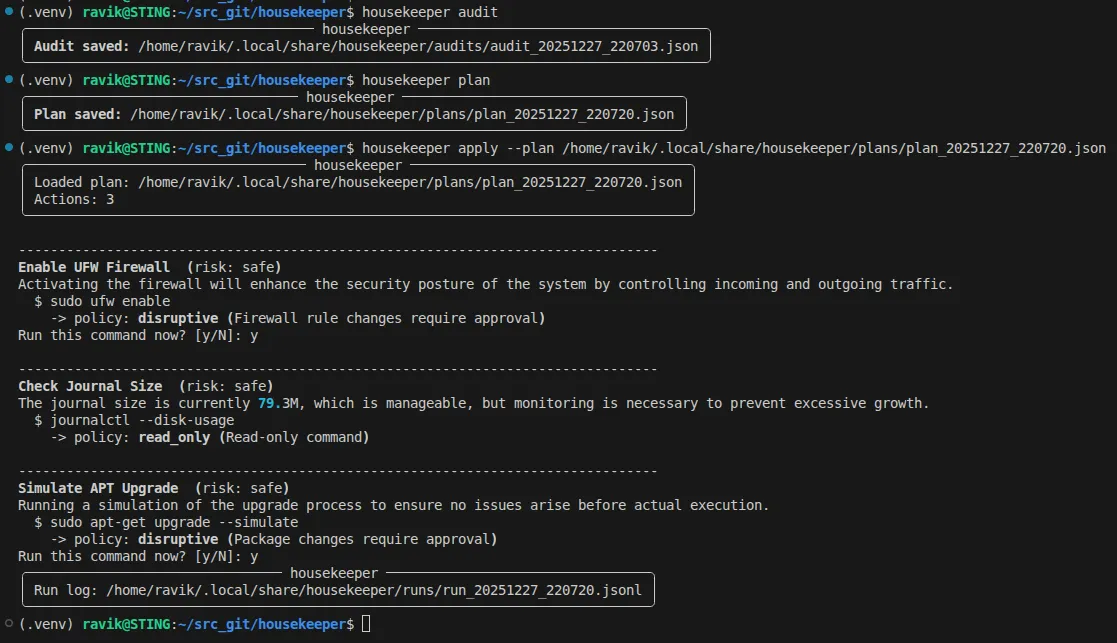
End-to-end execution of Housekeeper
Why Autonomous AI Breaks Down in Real Systems
Autonomy sounds attractive because it removes friction.
But real systems are full of properties that autonomous agents struggle with:
- Side effects
- Partial failures
- Irreversible actions
- Context that’s hard to infer
- Commands that are “safe” only in the right situation
Restarting a service might fix one issue and trigger another. Cleaning logs might delete information you need tomorrow. Upgrading packages might silently break drivers.
In production environments, we don’t tolerate this kind of blind action. We require audits, plans, approvals, and rollbacks.
So why would we lower the bar just because the operator is an AI?
Thinking Like an SRE, Not an Agent Designer
I come from an SRE mindset, and one habit is deeply ingrained:
Observe first. Then plan. Then act.
No SRE logs into a system and starts “fixing things” immediately. They collect signals, understand the state, propose actions, and get approval.
So instead of building an autonomous agent, I built Housekeeper—a terminal-based assistant designed to behave like a careful SRE.
Not an executor. A reviewer.
Housekeeper’s Core Model: Audit → Plan → Apply
Housekeeper is intentionally boring in its design:
audit → plan → applyAnd that’s exactly why it works.
Audit: Read-Only, Always
The assistant starts by collecting system signals.
(.venv) ravik@STING:~/src_git/housekeeper$ housekeeper audit
╭──────────────────────────────────── housekeeper ────────────────────────────────────╮
│ Audit saved: /home/ravik/.local/share/housekeeper/audits/audit_20251227_200202.json │
╰─────────────────────────────────────────────────────────────────────────────────────╯
Behind the scenes, this gathers things like:
- package upgrade health
- disk usage and journal growth
- failed systemd units
- firewall status
- reboot-required signals
- SSD trim state
Nothing mutates the system. No sudo. No side effects.
For most personal machines, this alone surfaces issues people didn’t know existed.
Plan: AI That Explains Itself
Next, the AI analyzes the audit and produces a plan.
(.venv) ravik@STING:~/src_git/housekeeper$ housekeeper plan
╭────────────────────────────────── housekeeper ───────────────────────────────────╮
│ Plan saved: /home/ravik/.local/share/housekeeper/plans/plan_20251227_200226.json │
╰──────────────────────────────────────────────────────────────────────────────────╯
A plan isn’t just commands—it’s structured reasoning.
Actions 3:• Simulate package update
Rationale: Ensure system is ready for upgrades
Risk: safe• Clean up journal logs
Rationale: Reduce disk usage from system logs
Risk: safe• Run fstrim to optimize disk usage
Rationale: Improve SSD performance
Risk: safeCrucially:
The AI cannot execute anything.
It makes a case. It does not take action.
Apply: Policy + Permission
This is where discipline really shows up.
(.venv) ravik@STING:~/src_git/housekeeper$ housekeeper apply --plan /home/ravik/.local/share/housekeeper/plans/plan_20251227_200226.jsonEach command is evaluated against a strict policy and shown for approval:
╭─────────────────────────────────── housekeeper ───────────────────────────────────╮
│ Loaded plan: /home/ravik/.local/share/housekeeper/plans/plan_20251227_200226.json │
│ Actions: 3 │
╰───────────────────────────────────────────────────────────────────────────────────╯

--------------------------------------------------------------------------------
Simulate APT Update (risk: safe)
To ensure the system is up to date and check for any potential issues with package management.
 $ sudo apt update -y
 -> policy: safe (sudo apt operation (approval required))
Run this command now? [y/N]: y
 $ sudo apt upgrade -s
 -> policy: disruptive (Package changes require approval)
Run this command now? [y/N]: y
Even safe commands require confirmation.
Disruptive commands are clearly flagged:
Review UFW rules (risk: safe)
To ensure the firewall is configured correctly and no unnecessary ports are open.
 $ sudo ufw status
 -> policy: disruptive (Firewall changes require approval)
Run this command now? [y/N]: y
Nothing runs “just because the AI said so”.
Why Permission Is Not Friction
A common argument against human-in-the-loop systems is that they’re slow. That assumes speed is the primary goal. In system operations, the real goal is trust.
When an assistant explains:
- why an action is suggested
- what exactly will happen
- how risky it is
…you start trusting it.
Ironically, Housekeeper feels more capable than autonomous agents because it’s predictable. I always know what it’s about to do.
A Practical Critique of Autonomous AI Agents
This isn’t an anti-AI argument. It’s a rejection of blind autonomy in high-impact environments.
Autonomous agents work well when:
- actions are reversible
- failure is cheap
- the blast radius is small
System maintenance is the opposite. Here, intelligence without accountability is a liability.
AI shines when it:
- analyzes complex state
- surfaces hidden risks
- proposes well-reasoned actions
- explains trade-offs clearly
It fails when it:
- assumes context
- executes without consent
- optimizes for completion over correctness
Housekeeper intentionally avoids that trap.
Policy Beats Prompting
One of the most important lessons from building this system:
Safety must live in code, not in prompts.
No prompt can replace:
- command allow-lists
- hard blocks for destructive operations
- explicit sudo rules
- risk classification enforced by logic
The AI can suggest anything. The policy decides what’s allowed.
This separation is what makes the system reliable.
What Building Housekeeper Changed for Me
Working on this project shifted how I think about AI entirely.
AI is not a replacement for operators. It’s a force multiplier for judgment.
The best role for AI in system operations isn’t:
- autonomous executor
- fixer
- self-directed agent
It’s:
- planner
- reviewer
- advisor
- second brain
Exactly like a Senior SRE sitting next to you, saying:
“Here’s what I see. Here’s what I’d recommend. You decide.”
The Bigger Lesson
We don’t need smarter AI agents. We need better-designed ones.
AI that:
- knows its boundaries
- respects permission
- logs everything
- accepts oversight
- optimizes for correctness, not autonomy
Discipline isn’t a limitation. It’s what makes intelligence usable.
Final Thought
Housekeeper is not flashy.
It doesn’t surprise me. It doesn’t act on its own. It doesn’t pretend to be in charge.
And that’s exactly why I trust it.
AI doesn’t need autonomy—it needs discipline.
Originally published on Medium on December 27, 2025.